
Key Takeaways
- Smart speakers listen locally at all times but only for the wake word, not general conversation.
- Audio is sent to the cloud only after the wake word is detected.
- A small, low-power chip handles local detection without recording or storing audio.
- False activations happen when ambient sounds closely resemble the wake word.
- Most smart speakers let you review and delete your stored voice recordings.
Wake word detection
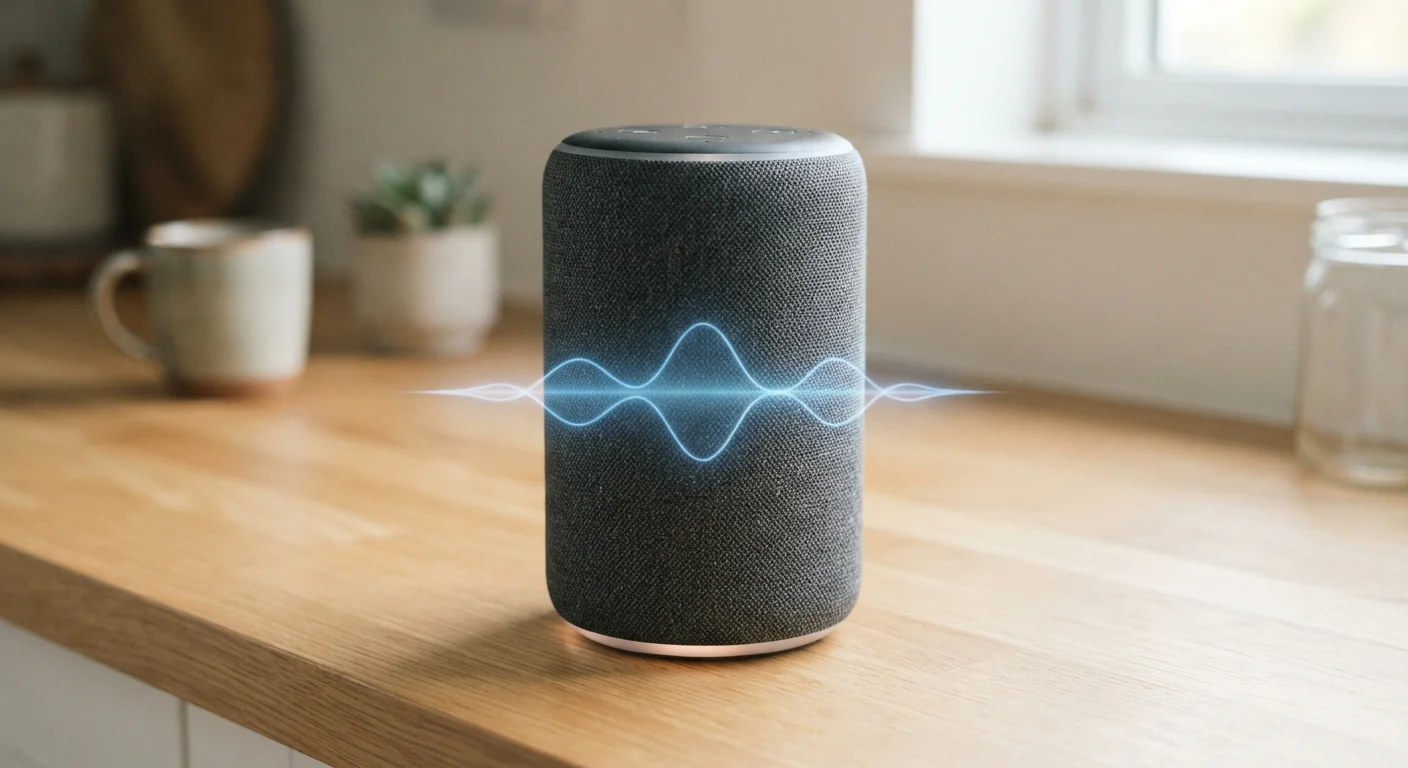
A wake word (sometimes called a trigger phrase) is the spoken cue that activates a smart speaker, such as 'Hey Alexa' or 'OK Google.' Before you say it, the device is not recording or sending audio to the internet. Instead, a small, low-power chip inside the speaker continuously analyzes sound locally to detect that specific phrase. Only after the wake word is recognized does the speaker start streaming audio to a cloud server to process your actual request.
Wake word detection runs on a dedicated always-on processor called a DSP (digital signal processor), which uses a compact neural network trained to match the acoustic pattern of the trigger phrase.
Two stages of listening
Every smart speaker operates in two distinct phases. In the first phase, a dedicated low-power chip inside the device runs continuously, analyzing incoming sound against a small model of what the wake word sounds like. This happens entirely on the device, without a network connection. The chip consumes very little power because its only job is to match one specific acoustic pattern.
When that match occurs, the device moves to the second phase: it opens a microphone stream and begins sending audio to the manufacturer's cloud servers. Those servers run sophisticated speech recognition and natural language processing to understand what you actually asked. The split exists because full cloud processing for every ambient sound would be slow, expensive, and far more invasive than users would accept.
On-device processing varies by manufacturer
Some newer devices have expanded on-device capabilities, allowing certain simple commands to be completed without any cloud connection at all. However, for the majority of requests on most current smart speakers, the cloud is still required to understand and respond to what you said.
What the device hears before activation
The on-device chip listens to everything in its range, but it does not store or transmit what it hears. Think of it like a smoke detector: it monitors air constantly but only triggers when a specific condition is met. In the same way, the detection chip processes audio in a rolling window of roughly one to two seconds, then discards it. Nothing from that window is written to memory or sent anywhere unless the wake word pattern appears.
The model running on that chip is a compact neural network, trained on thousands of recordings of the target phrase spoken by different people in different environments. It converts raw audio into a numerical representation and compares it against stored parameters. If the match score crosses a set threshold, the chip signals the main processor to begin recording.
Why false activations happen
The threshold the chip uses is deliberately set to favor sensitivity over precision. A model tuned too strictly would miss valid wake words spoken softly or with an accent. One tuned too loosely will occasionally fire on similar-sounding phrases. Manufacturers calibrate this balance through large-scale testing, but no model eliminates false activations entirely.
Television dialogue, podcasts, and casual conversation can all contain syllable combinations close enough to the wake word to clear the threshold. When that happens, the speaker sends a short clip to the cloud just as it would for a real command. This is the scenario most often raised in privacy discussions about smart speakers.
Review your stored voice recordings
Most smart speaker platforms let you see and delete audio clips captured after wake word activations. Checking the privacy or history section of the companion app periodically gives you direct control over what the manufacturer retains. You can usually also turn off the option to have recordings used for product improvement.
What happens in the cloud
Once audio reaches the server, a much larger speech recognition system transcribes it and a natural language model interprets the intent. The server then returns a response, which the speaker plays back within about one second under normal network conditions.
Manufacturers typically store a short audio clip and a text transcript of each interaction. The stated purposes include improving speech recognition accuracy and personalizing responses. Most platforms provide a web interface or companion app where users can listen to stored clips, delete individual recordings, or opt out of having recordings used for model training. The specifics vary by manufacturer, so checking your device's privacy settings directly gives you the clearest picture of what is retained and for how long.