
Federated Learning vs. Centralised AI Training: A Privacy Trade-off Worth Understanding
Key Takeaways
- Federated learning trains AI models without raw user data ever leaving individual devices.
- Centralised training sends data to shared servers, where it can be processed at greater scale.
- Federated models often perform less accurately because they learn from smaller, fragmented data slices.
- Neither approach is inherently secure: both carry distinct privacy risks that depend on implementation.
- The right method depends on the sensitivity of the data and the accuracy requirements of the application.
Option A
Federated Learning
The privacy-conscious approach that keeps raw data on your device.
Best for: Applications where user data is sensitive and should not leave the device, such as mobile keyboards and health monitors.
Option B
Centralised AI Training
The established method that pools data on shared servers for maximum model power.
Best for: Scenarios where large, diverse datasets are needed and privacy concerns are manageable, such as enterprise analytics and large language models.
If you use a mobile app that handles sensitive health or financial data
Federated Learning
Raw personal data stays on your device. The app improves its model without your records being stored on a remote server.
If a developer needs the most accurate model possible and data sensitivity is low
Centralised AI Training
Access to a large, unified dataset produces more accurate and generalised models, especially for complex tasks like language understanding.
If you want to understand which AI systems are more privacy-respecting by design
Federated Learning
Federated learning limits exposure by keeping raw data local, though it is not a complete privacy guarantee on its own.
How each approach actually works
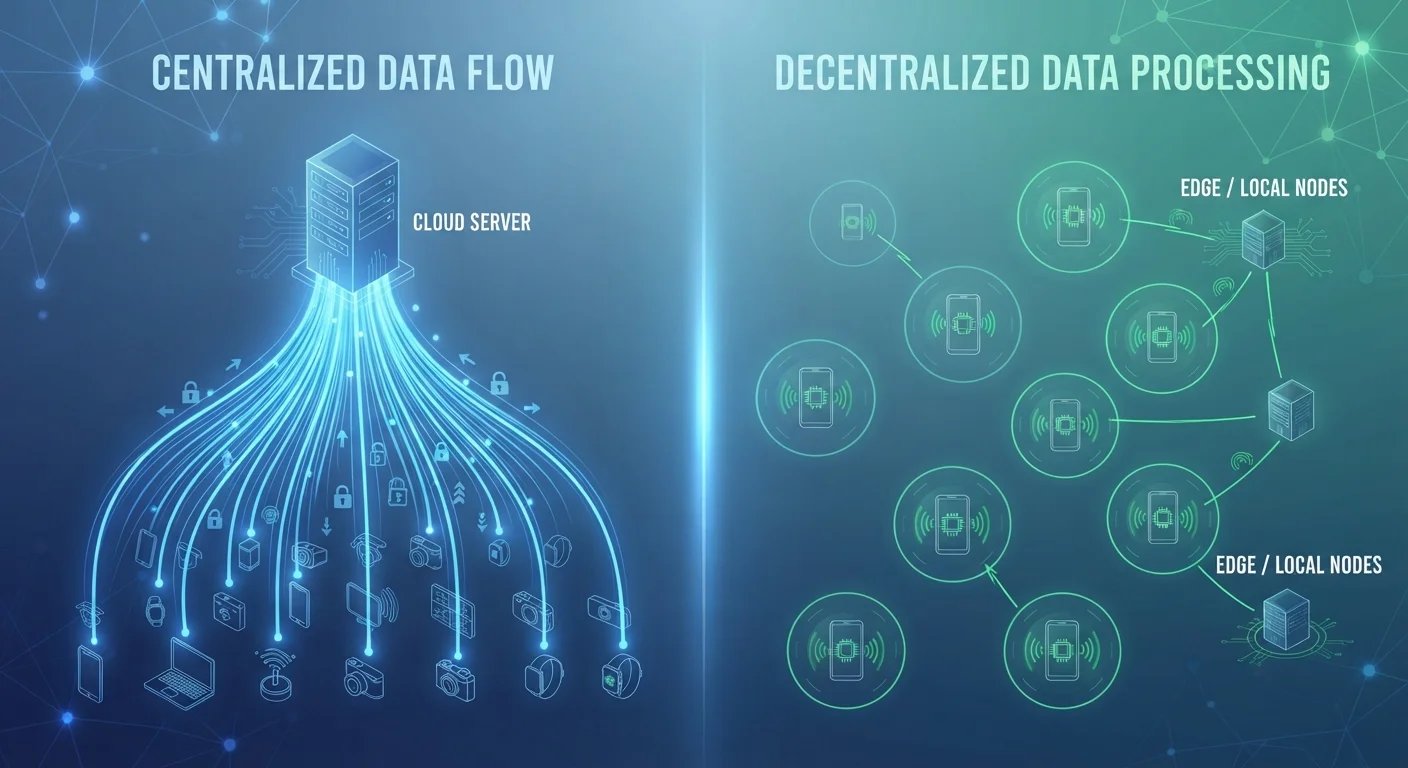
Centralised AI training is the older and more common method. A company collects data from users, applications, or sensors and uploads it to servers it controls. Engineers then train a model on that pooled dataset. The model sees everything at once, which helps it learn broad patterns across millions of examples.
Federated learning works differently. Instead of moving data to a central server, the model itself travels to each device. Your phone, for example, trains a local version of the model on your own data. Only the updated model weights (mathematical adjustments, not the underlying data) are sent back to a coordinating server. Those updates are aggregated across thousands of devices to improve the shared model, and the cycle repeats.
Google described this architecture in a 2017 research paper as a way to improve Gboard, its mobile keyboard, without logging what users type. The same general approach is now used in other on-device applications, including some medical wearables and voice assistants.
| Criterion | Federated Learning | Centralised AI Training |
|---|---|---|
| Where data is processed | On the user's device | On remote servers |
| Raw data leaves device | No | Yes |
| Typical model accuracy | Lower due to data fragmentation | Higher with large pooled datasets |
| Breach risk for raw data | Lower (no central store) | Higher (centralised data target) |
| Technical complexity | High (requires on-device compute) | Moderate (established infrastructure) |
| Common use cases | Mobile keyboards, health wearables | Large language models, search engines |
The privacy picture
Centralised training concentrates risk. When raw data sits on a server, a breach, a subpoena, or a policy change can expose it. Users often have limited visibility into what was collected or how long it is kept. This connects to broader data-tracking practices covered in how websites follow you around.
Federated learning reduces that exposure. Because raw records never leave the device, there is no central database of personal inputs to steal or misuse. That is a meaningful structural advantage.
However, federated learning is not privacy-proof. Researchers have shown that shared model updates can sometimes leak information about the training data through a technique called gradient inversion. Combining federated learning with additional methods, such as differential privacy (which adds statistical noise to updates) or secure aggregation (which hides individual updates from the server), addresses some of these weaknesses, though each adds complexity and can reduce model accuracy further.
Differential privacy adds another layer
Differential privacy is a mathematical technique that adds carefully calibrated random noise to data or model updates before they are shared. The goal is to make it statistically impossible to identify any individual's contribution to a model. It is often combined with federated learning to further reduce re-identification risks, though the added noise does reduce model accuracy to some degree. Apple and Google both publish documentation on their use of differential privacy in certain products.
Performance and practical trade-offs
Centralised training produces better models in most benchmarks. The coordinating server sees a consistent, large, and diverse dataset. It can run more training cycles, correct errors faster, and generalise across edge cases. The large language models behind today's AI assistants are trained centrally, partly because the scale of data required makes a distributed approach impractical.
Federated models face several constraints. Data across devices is heterogeneous: one user's typing patterns may look nothing like another's, and some devices contribute far more data than others. This statistical fragmentation can make the model less reliable. Devices must also stay online and have sufficient battery and processing power during training, which introduces gaps in participation.
For many real-world applications, these trade-offs are acceptable. A keyboard that predicts your next word well enough, without reading your messages, may serve users better than a marginally more accurate keyboard that logs everything. The calculus changes when accuracy is safety-critical, such as in medical diagnosis tools.
Understanding where AI outputs can go wrong regardless of training method is worth exploring separately; AI hallucinations and why they happen covers that ground. For a broader look at how training data shapes model quality, synthetic data in AI training is a useful companion read.
What this means for everyday users
Most people do not choose between these methods directly. The choice is made by the developers of the apps and services you use. What you can do is look for products that document their data practices clearly and state whether on-device or server-side training applies.
Privacy labels in app stores, terms of service sections on data retention, and published research papers (as Google released for Gboard) are places to look, though not all developers provide this detail. The Internet and Privacy hub has more on evaluating how services handle your data.
The broader point is that AI training is not a single thing. How a model learns determines what data exists to be exposed, retained, or misused. Federated learning narrows that exposure structurally; centralised training trades that narrowing for accuracy and scale. Neither choice is invisible to you as a user, even if it operates far in the background.